By Eric Richmond
On September 20, 2026, Duane Forrester published “LLMs Are Time Machines That Don’t Tell You How Far You Went” in Duane Forrester Decodes.
His central image is simple and difficult to forget:
An LLM takes present-you, the version with a question, and hands back future-you: the version with a decision.
The library became search. Search became the answer engine. The starting point stayed the same. The destination stayed the same. Almost all the travel disappeared.
The uncertainty underneath is not new. What is new is quieter.
What disappeared from the journey
The old information journey was never only transportation. It carried signals about the quality of what you were receiving.
Three books and no journal articles suggested that a subject might be thin. Sources that contradicted one another suggested that it was contested. A search that returned nothing suggested that you were entering unmapped territory.
Time mattered, too. A question that took four hours to investigate felt different from one answered in four minutes.
Nobody had to consciously read these signals. They were simply present in the process. They shaped how firmly you committed to the answer.
Forrester calls this path metadata: the byproduct of the journey that helped you understand how much an answer was worth.
An answer engine strips much of it away. It can return the same fluent, confident prose whether the evidence underneath is deep, current, contradictory, or nearly absent.
You arrive at the destination without being told how far you traveled, or what you passed along the way.

The research caught up
For years, this was a reasonable concern. In 2025 and 2026, the research became harder to dismiss.
Shiri Melumad and Jin Ho Yun, marketing professors at Wharton, ran seven experiments involving 10,462 participants. Their findings were published in PNAS Nexus in October 2025 in “Experimental evidence of the effects of large language models versus web search on depth of learning.”
Participants learned about ordinary topics such as planting a vegetable garden or spotting financial scams. Some used an AI summary. Others used standard Google-style links. Then they wrote advice for someone else.
The AI-summary group:
- Knew less about what they had received
- Spent less time engaging with it
- Produced advice that was sparser and less original
- Produced advice that readers were less likely to take
The underlying facts were held constant. In one version, the AI supplied live web links alongside its answer. Participants still did not click them.
Pew Research Center found a related pattern in real browsing behavior. Its July 2025 analysis tracked 900 U.S. adults across 68,879 Google searches during March 2025.
When an AI summary appeared:
- A traditional search result was clicked on 8% of visits, compared with 15% when no summary appeared
- A source cited inside the AI summary was clicked on roughly 1% of visits
- The browsing session ended on 26% of pages with a summary, compared with 16% without one
Pew is careful about the limits of this finding. It describes an association, not proven causation. The study covered one month, U.S. users, and Google searches only.
Still, the methods converge. One study controlled the experience. The other observed it in the wild. Different methods, similar destination: when the summary arrives, the journey becomes less likely to continue.
The pattern also has older roots. In 2015, Yale researchers ran nine experiments with more than 1,000 participants and found that searching the internet inflated how much people believed they knew. The effect appeared even when searchers and non-searchers saw identical content, and even when searches produced no answer.
That complicates any romantic view of the old web. Search never guaranteed understanding. It did, however, leave behind friction, elapsed time, and visible variety in the sources.
A 2025 paper from Microsoft Research and Carnegie Mellon surveyed 319 knowledge workers about 936 real uses of AI at work. Higher confidence in AI was associated with less reported critical thinking; higher confidence in one’s own ability was associated with more.
Forrester flags the important caveats: the study is self-reported and correlational, not causal. He also notes that one of the co-authoring institutions sells a generative AI product. That disclosure does not invalidate the work. It tells us how carefully to interpret it.
Dirk Lewandowski’s 2026 information-regret study points in a similar direction from a smaller, more exploratory sample.
The correction that used to happen for free
This is where the issue stops being only about users and becomes an issue for anyone who publishes.
Under the old model, a thin or wrong answer was often survivable because the journey repaired it.
Someone read a bad summary, kept going, landed on the actual source page, and swapped the wrong version for the right one.
Nobody designed this mechanism. It cost nothing. It ran on somebody else’s curiosity. And it fired millions of times a day.
The reader corrected the summary by reaching the source.
That process functioned as the immune system of the information economy.
At a source-click rate of roughly 1%, it does not fire often enough to perform that job.

The expensive asymmetry
The old repair mechanism was free, automatic, and immediate.
Its replacement is not.
Now, a brand has to publish the evidence, maintain the evidence, wait for it to be crawled or retrieved, and hope it is weighted correctly by a platform it does not control.
There is no guaranteed timeline. There is no automatic confirmation that the correction worked.
A mechanism that once cost nothing and fired in seconds has been replaced by one that costs real money and fires slowly, if it fires at all.
That is the asymmetry.
Citation is presence, not traffic
If roughly one visit in a hundred produces a click on a cited source, then treating AI citation as a referral channel values it incorrectly.
The value is not primarily the visit that escapes the answer.
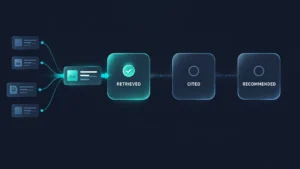
The value is being inside the answer a person acts on.
That means AI search visibility has to be measured at the answer layer, not only through the small stream of referral traffic that remains visible in analytics.
This is also why brand knowledge governance matters. The question is no longer only whether your content can be found. It is whether the information an AI system has about your brand is accurate, current, and consistently represented.
The reader who arrives pre-answered
Forrester makes another important observation: the person who reaches your site or sales call may not be uninformed. They may be confidently underinformed.
He explicitly presents this as his own inference, not as a finding from the studies above.
That distinction matters. None of those papers tested marketing funnels or content strategy.
But the implication is clear enough to examine.
A reader who believes the research is already complete does not behave like a curious researcher. Beginner content may feel too basic. Advanced content may assume understanding the reader does not actually possess.
The person arrives further along in confidence than in comprehension.
This changes what effective content has to do. It must not only explain. It must establish what is true, show what is missing, and give the reader a reason to verify rather than simply continue trusting the summary they already received.
The mirror
I use these systems too. So do you.
If a strategy deck, competitive analysis, or recommendation came out of a model’s synthesis, then it may contain the same sparser, less original output that Melumad and Yun measured.
And we may be more certain about it than the process earned.
That is the uncomfortable part. AI can take us from question to decision in seconds. The decision may be useful. But the speed of the process can make confidence feel like evidence.
The answer is not to reject these tools. It is to understand what they remove, and to build verification back into the workflow.
Verification is the replacement
If the free correction loop is gone, what replaces it?
Not detection alone.
Detection without confirmation is just a dashboard.
The valuable loop is:
Monitor → detect → diagnose → fix → verify
The final step is now the scarce one.
Where CiteMetrix fits
At CiteMetrix, we built the product around that closed loop, not around traffic reporting alone.
Hallucination Detection checks AI responses against verified Brand Facts and identifies five error types:
- Incorrect Fact
- Outdated Info
- Fabricated Claim
- Misleading Context
- Critical Omission
Each error receives a Minor, Moderate, or Critical severity level and routes to a contextual fix. It is brand-specific AI accuracy monitoring, not a general enterprise hallucination solution. Unverified facts and correct answers are tracked separately to avoid turning uncertainty into false alarms.
Source of Truth lets a team verify a fact once and use it as the baseline for monitoring. From that verified data, CiteMetrix generates llms.txt and schema.org markup deterministically, not through AI-written guesses. A verified-only publishing gate is restricted to Owners and Admins, and drift detection can catch a generated file that was never uploaded.
Correction Proof then answers the question the old web answered automatically: did the AI platform actually update its answer after the correction?
Professional plans and above include Hallucination Watch, which rechecks flagged issues daily until the AI stops repeating them.
CiteMetrix also measures Accuracy and Brand Perception: what platforms say about your brand and how they frame it.
ModelScore™ reflects the same distinction between presence and traffic. Its four components are:
- Mention Score, 45%: citations across nine engines, weighted by sentiment and prominence
- Brand Demand, 20%: branded searches from Google Search Console
- Authority Transfer, 20%: AI-referred traffic from GA4 or Adobe Analytics
- Technical Readiness, 15%: schema, crawlability, and
llms.txt
Authority Transfer is important, but it is not the whole score. Referral traffic is the observable trickle. Influence often happens inside the answer.
CiteMetrix includes nine built-in features, nine monitored AI platforms on every plan (ChatGPT, Perplexity, Claude, Google AI Overview, Google Gemini, xAI Grok, Mistral, DeepSeek, and Copilot) and starts at $79 per month.
Everything Included, Nothing Extra.

The time machine still works
Forrester’s metaphor holds.
The time machine takes you from a question to a decision. It is genuinely useful. But it drops you somewhere without telling you how far you traveled, what evidence was skipped, or whether the answer changed after someone corrected it.
Understanding that machinery is the beginning of restoring what was lost.
The future of AI search visibility will not be won by detecting more mentions alone. It will be won by knowing which claims are true, which claims are wrong, what changed, and whether the correction actually landed.