By Eric Richmond, Founder of CiteMetrix
For twenty years, “winning” in search meant being in position one.
The goal was simple: rank above the other results, earn the click, and move the buyer toward a decision.
Conversational search changes that sequence.
When a buyer asks ChatGPT, Perplexity, Claude, Gemini, or another AI assistant a question, the first answer is not the decision. It is the opening bid.
The buyer who is still asking questions has not chosen anything yet.
They are clarifying. Adding constraints. Comparing options. Looking for proof. Testing whether the recommendation holds up.
A brand can be named first in the opening answer and still lose the buyer five questions later.
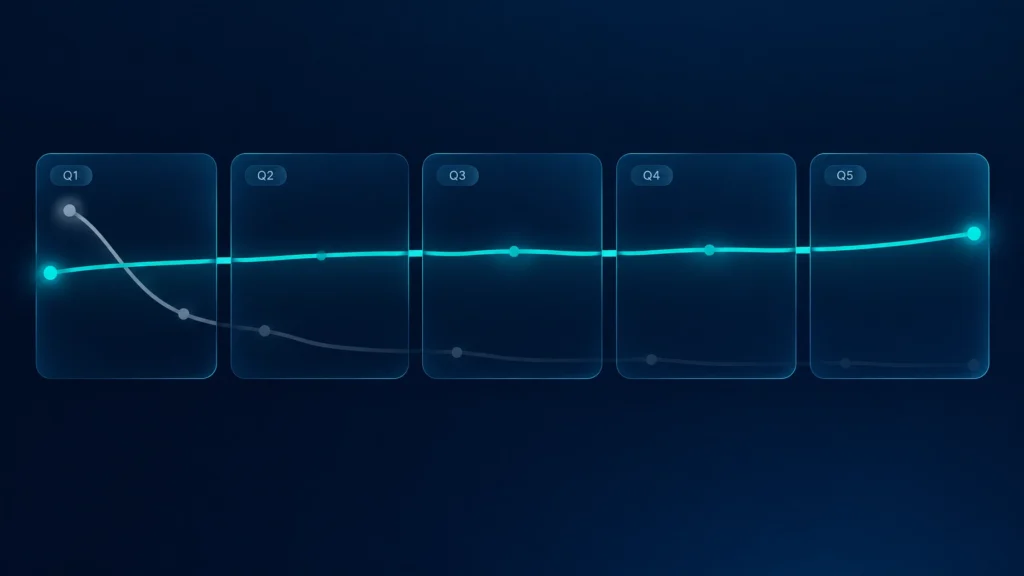
That is the strategic gap most AI visibility programs are not yet measuring: not whether your brand appeared once, but whether your position survived the conversation.
AI visibility is becoming a sequence, not a snapshot
Search Engine Land made this framing explicit in its September 15, 2026 article, “The follow-up query: Rethinking SEO for conversational search”.
The article’s central argument is that search has become a chain of questions rather than a single query. The first question establishes context. The follow-up questions reveal intent.
That distinction matters because the opening question is usually the buyer’s least informed question.
It is broad. It is generic. It contains the fewest constraints. It is also where nearly every credible competitor in the category is likely to appear.
“Which project management tools are best for a growing team?” produces a wide field.
“What works for a 40-person team with strict permission controls and a limited implementation budget?” produces a shortlist.
“Which of those has the strongest reporting, the easiest migration path, and reliable support?” begins to produce a decision.
The first answer creates awareness. The follow-ups create preference.
Why the opening answer is the least valuable moment
Brands naturally over-index on the opening answer because it is easy to understand and easy to report.
Were we mentioned?
Were we cited?
Were we listed first?
Those questions matter. But they describe the qualifying round, not the outcome.
The opening question usually gives an AI platform permission to describe the category. It does not require the platform to defend a recommendation.
The follow-up is different. It introduces pressure:
- Does the product fit a particular use case?
- Does the company meet a specific requirement?
- How does it compare with another option?
- Is the claim supported by evidence?
- What should the buyer do next?
This is where a brand’s positioning either becomes useful or falls apart.
A brand may be introduced as “a leading option” and then disappear when the buyer asks about pricing transparency. It may be recommended for enterprise teams and then fail when the buyer asks about implementation. It may be described accurately but so generically that the buyer has no reason to choose it.
The opening mention gets attention. Durable presence earns consideration.
What durability means in AI search
Positioning durability is the ability to remain present, accurate, and favorably framed as a conversation becomes more specific.
It means your brand can survive:
- New constraints
- Direct comparisons
- Requests for evidence
- Questions about limitations
- Scrutiny of pricing, support, implementation, or fit
Durability is not the same as appearing in every answer. A brand that appears five times with inconsistent or misleading descriptions is not necessarily stronger than a brand that appears three times accurately.
The goal is a consistent position that remains useful as the buyer’s requirements become clearer.
| Appearing once | Surviving the conversation |
|---|---|
| Present in the opening category answer | Present when the buyer adds constraints |
| Broad or generic description | Specific, defensible positioning |
| One platform or one prompt | Consistent visibility across relevant platforms |
| Mention may be favorable or neutral | Framing remains favorable and accurate |
| Success is reported as an event | Success is evaluated as a pattern over time |
| Often owned by SEO or content | Requires marketing, product, legal, support, and operations |
This is why AI visibility should be treated as a durability problem, not only a citation problem.

The three ways brands lose durability
1. Factual fragility
A brand makes it through the opening answer because the AI knows the category association.
Then the buyer asks for a specific fact.
The price is outdated. A feature is described as available when it was discontinued. A certification is attributed incorrectly. A product limitation is omitted. A claim cannot be verified.
The brand becomes risky to recommend.
CiteMetrix’s Accuracy & Hallucination Detection is designed to surface these failures. It categorizes five error types:
- Incorrect Fact
- Outdated Info
- Fabricated Claim
- Misleading Context
- Critical Omission
Each error receives a Minor, Moderate, or Critical severity level, with contextual remediation routed according to the type of problem.
Detection is included from Starter. Professional and higher plans add Hallucination Watch, which automatically rechecks flagged issues daily until they are resolved.
The important distinction is that CiteMetrix separately tracks unverified facts and correct answers. That helps teams avoid treating every unfamiliar AI statement as a hallucination.
A durable position requires more than being known. It requires being correct when the buyer asks for specifics.
2. Structural fragility
Sometimes the business knows the answer, but the site does not state it in a way AI systems can reliably retrieve and reuse.
The information may be buried in a PDF, implied through marketing language, scattered across several pages, or absent from structured data. The buyer asks a qualifying question, and the AI cannot connect the requirement to the brand.
This is structural fragility.
A site can be technically available and still fail to communicate its most important facts clearly enough for machine interpretation.
CiteMetrix’s Source of Truth addresses this at the governance layer. Teams maintain verified Brand Facts in one repository. Those same facts are used to generate llms.txt and schema.org markup deterministically.
The verified-only publish gate is controlled by an Owner or Admin. That matters because a machine-readable fact is still a public claim. If it is wrong, the problem spreads faster.
Source of Truth also includes internal and live drift detection. Correction Proof reports whether an AI platform actually updated its answer after the underlying fact was fixed.
That closes an important loop: the company changes the fact, publishes the correction, and verifies whether the buyer-facing answer changed.
3. Framing fragility
The third failure is subtler.
The information is accurate. The brand is present. Nothing is technically wrong.
But the framing is generic, unfavorable, or disconnected from the buyer’s actual concern.
A professional services firm may be described as “a general consultancy” when it has a strong specialization. A software company may be called “feature-rich” while the buyer is looking for easy implementation. An e-commerce brand may be mentioned but not recommended because the AI cannot explain why it is the right fit.
This is where presence and preference diverge.
CiteMetrix tracks Brand Perception and Model Sentiment to show how AI platforms characterize a brand, not just whether they mention it. A citation can be positive, neutral, or negative. A brand can have visibility and still be framed in a way that weakens the buying case.
Durability therefore requires a position that is both accurate and useful.
Durable positioning is a company-wide responsibility
It is tempting to assign this work to the content team.
Content teams can clarify language, improve page structure, publish supporting evidence, and resolve gaps. But they cannot manufacture durable facts.
The answer a buyer receives is shaped by the entire company:
- Marketing defines the positioning and category context.
- Product determines which capabilities are real and current.
- Legal governs claims, certifications, and approved language.
- Customer support reveals recurring questions and points of confusion.
- Sales hears the constraints buyers use to narrow a shortlist.
- Operations determines whether the promised experience is actually delivered.
- Reviews and third-party sources influence how the market describes the brand.
This is why AI visibility belongs inside a broader discipline of brand knowledge governance.
A marketing page can claim fast implementation. But if customers consistently report a difficult onboarding process, the durable position will eventually reflect that tension.
A company can publish a pricing page that says one thing while sales decks, review sites, and support documentation say another.
AI systems do not experience these as separate departmental problems. They become one brand representation.
The goal is not to make every source say exactly the same sentence. It is to make the important facts consistent enough that the brand survives scrutiny.

A strategic framework for conversation durability
This is not a call to write five versions of every page or manually script every possible AI conversation.
The strategic question is more useful:
Which conversations matter enough for your brand to survive?
Start with three decisions.
Choose the conversations that matter
Not every prompt deserves equal investment.
Focus on the conversations that influence high-value recommendations, create competitive risk, or expose a meaningful gap between how the company sees itself and how AI describes it.
For one brand, that may be product comparisons. For another, it may be provider recommendations, compliance questions, implementation concerns, or price-sensitive buying journeys.
Identify the facts that must survive scrutiny
For each important conversation, determine which facts should remain intact as the buyer gets more specific.
These may include:
- Target customer and use case
- Pricing model
- Product limitations
- Implementation requirements
- Geographic or regulatory coverage
- Support model
- Differentiating capabilities
- Evidence behind major claims
These are not merely content topics. They are the facts that protect the brand from disappearing or being misrepresented at the point of decision.
Build for repeatability, not a perfect first answer
The perfect opening answer is not the objective.
A durable program gives AI systems enough consistent, verifiable information to keep representing the brand accurately across changing contexts.
That means connecting public content, structured data, verified facts, third-party proof, and operational reality. It also means monitoring how the position changes instead of assuming that one successful prompt represents the whole market.
How to measure durability
ModelScore is a useful starting point because it combines four dimensions of AI visibility:
- Mention Score, 45%: citation frequency, with sentiment and prominence weighted across nine engines
- Brand Demand, 20%: branded searches measured through Google Search Console
- Authority Transfer, 20%: AI-referred traffic from GA4 or Adobe Analytics
- Technical Readiness, 15%: schema, crawlability, and
llms.txt
A brand that wants to understand durability needs more than one component.
Mention Score can show whether the brand appears. Model sentiment and Brand Perception help show whether the framing is favorable. Share of Voice shows how durability compares with competitors, by platform and over time.
Authority Transfer helps connect visibility to downstream traffic. Impact connects that visibility to business outcomes.
Content Change Tracker adds the operational context: page snapshots on every scan make it possible to attribute a citation movement to a specific content change, without pretending that correlation proves causation.

The practical companion, “The Follow-Up Query Is Where You Lose the Buyer”, covers the mechanics of measuring a multi-question chain. This piece is about the strategic reason to care: the first answer is only a qualifying round.
CiteMetrix brings the broader system together with nine features working as one platform, nine AI platforms on every plan, and no extra apps or add-ons. AI Coaching provides a personalized first-scan debrief, coaching cards, and a weekly AI consultant briefing so teams can move from signal to decision.
Business plans start at $79 per month, with everything included.
The new definition of winning
Winning in AI search is not being named first and then forgotten.
It is being present when the buyer adds a constraint. Accurate when they ask for proof. Relevant when they compare alternatives. Favorable when they decide what to do next.
The brands that perform best in conversational search will not necessarily have the most impressive opening answer.
They will have the most durable position.
See what AI says about your brand and get your ModelScore → citemetrix.com
Eric Richmond is the founder of CiteMetrix. He has spent nearly two decades in organic search and now helps brands understand how AI platforms describe, cite, and recommend them.